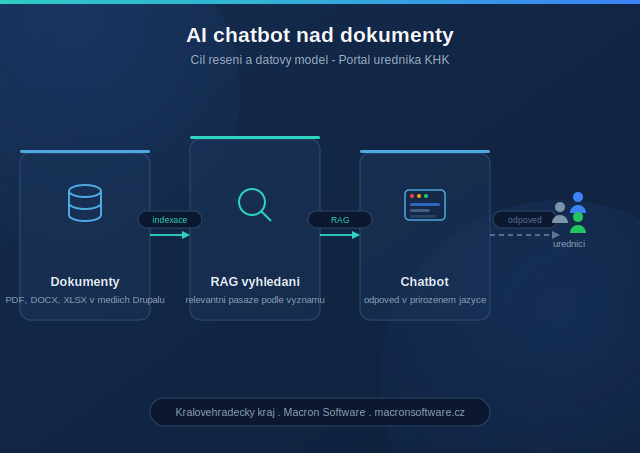
A chatbot for working with documents, not a generic assistant
The chatbot will be available to every signed-in employee directly inside the intranet, with the option to restrict it by user role. It will communicate in natural language and will be able to search, summarize, and cite the content of documents, including links for downloading them. What matters most is that it will know the content of every document uploaded to the intranet (PDF, MS Office and similar) along with their metadata, such as which section they are stored in, when they were published, and who uploaded them, and that this knowledge will be kept up to date automatically. The chatbot will also hold the context of the conversation, so users can ask follow-up questions and narrow down what they need.
RAG, embedding, and chunking in a nutshell
So that the chatbot answers from the real content of the documents rather than from the general knowledge of the language model, it uses RAG (Retrieval-Augmented Generation). For every question, the system first finds the relevant passages in the documents and only then passes them to the language model as context for the answer. For this purpose the documents are split into smaller logical parts, called chunks, and each part is turned by embedding into a vector representation that captures its meaning. These vectors are stored in a vector database, where a query can search them quickly by similarity of meaning rather than by matching words.
Documents as data: media in Drupal
The data comes from the existing implementation of the Civil Servant Portal in Drupal, where every document is stored as a separate media item with its own metadata: title, description, folder (section), the actual author, file type, and a record of who uploaded the document and when. The solution will process every published document of this type and will draw on both the text of the file itself and this metadata when answering.
The first design phase therefore ends with a clearly defined goal and a data foundation: a chatbot built on the documents stored in Drupal, extended with the RAG technique.
Series: AI chatbot in the Hradec Králové Region Civil Servant Portal